

You’ve probably had this happen: you write a prompt you’re genuinely proud of, generate an image, and think “okay, this is basically my final version, I just need to run it once more to lock in the details.” Then you accidentally run it on a different model, same exact prompt, not a word changed, and what comes back barely resembles the first one. Different face shape. Different linework. Different mood entirely. Same words, different picture.
That’s not a bug, and it’s not you doing something wrong. It’s the model doing exactly what it was trained to do, which is a different thing depending on which model you picked. It’s a little like handing the same written description to two different illustrators and being surprised when their finished pieces don’t match. The words were identical. The hand doing the interpreting wasn’t.
If you’ve never really thought about model choice as part of the creative decision, this is the article that explains why it probably should be, and why the model deserves roughly the same attention you’d give your actual prompt.
What Does the Model Actually Change?
A prompt is instructions. A model is the thing interpreting those instructions, and interpretation is never neutral. Two models given the identical prompt can differ in style, leaning toward soft painterly shading versus crisp cel-shaded linework. They can differ in prompt interpretation, one model might weight “dramatic lighting” heavily while another treats it as a minor suggestion. They can differ in how they render characters specifically, face shape, eye style, proportions, all shift depending on what the model learned to default to. They can differ in composition, framing a scene tightly versus pulling back for something wider. And they can differ in how much fine detail actually survives into the final image versus getting smoothed over.
It helps to think of a model less like a neutral tool and more like a collaborator with its own instincts. Ask two different illustrators for “a dramatic sunset scene” and you’d expect two different interpretations of “dramatic,” not because either one is wrong, but because they’re each bringing their own sense of what that word means. Models work the same way, just trained on a huge amount of visual data instead of years of personal artistic experience. None of this means one model is objectively better. It means each model has a personality, for lack of a better word, and that personality shapes your result just as much as your prompt does.
Choose Models by Task, Not by “Newest”

There’s a natural instinct to reach for whichever model just launched, on the assumption that newer automatically means better. Sometimes that’s true. Often it’s beside the point, because “better” isn’t really a single axis, it depends entirely on what you’re trying to make.
A model that excels at close-up portraits with strong facial detail isn’t necessarily the right pick for a complex multi-character battle scene, where composition and spatial coherence across several figures matters more than any single face. A model tuned for clean, readable single-subject illustrations might struggle with a busy scene full of background elements. A model built with manga-style panel composition in mind is going to handle that layout differently than one trained mostly on standalone character art. The “best” model is really “the best model for this specific task,” and that answer changes depending on what you’re generating that day.
Anime Style and Character Rendering
Anime as a visual category covers a lot of ground, soft shoujo-style linework, sharp seinen detail, painterly key-visual aesthetics, flat cel-shaded simplicity, and different models tend to gravitate toward different corners of that range based on what they were trained on. A model that renders soft, rounded character designs beautifully might flatten out sharper, more angular character concepts, and vice versa.
This matters most for character work specifically. If you’re designing an OC with a particular aesthetic in mind, delicate and ethereal, or bold and graphic, picking a model whose natural tendencies already lean that direction is going to save you a lot of fighting against the model’s defaults through prompt wording alone.
Prompt Following and Complex Scenes
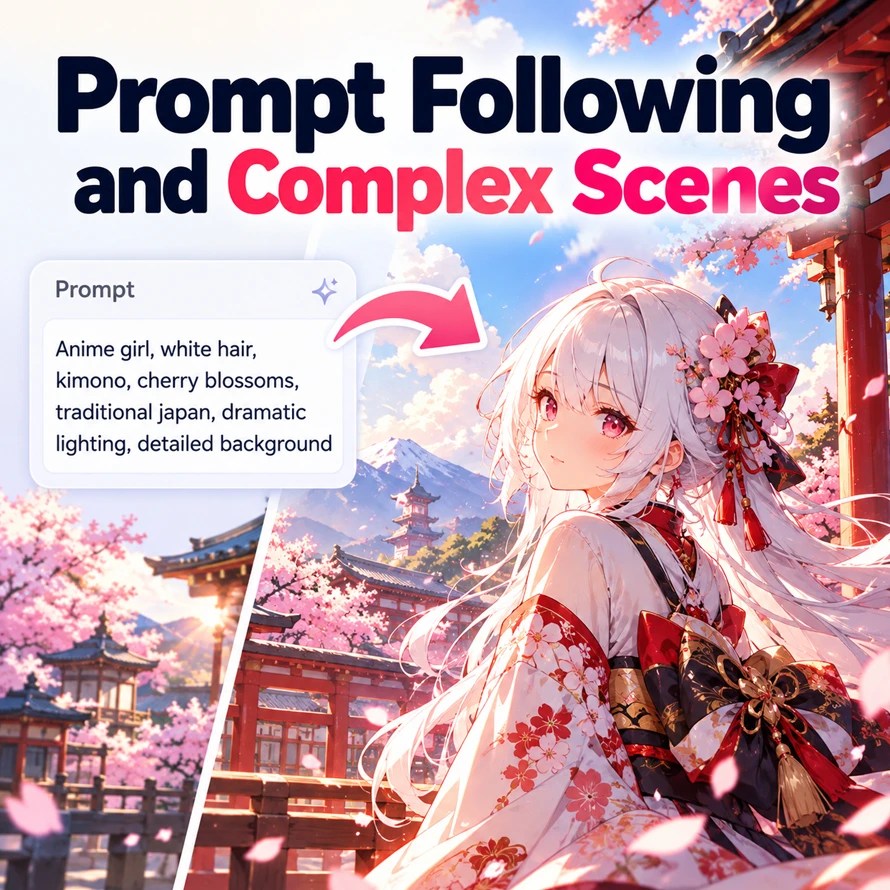
The more detailed your instructions, the more model behavior actually matters. A simple prompt, “anime girl, blue hair,” is forgiving, almost any anime-focused model can handle it reasonably well. A detailed prompt with specific character traits, a precise setting, particular lighting, and a specific mood is a much harder ask, and models vary quite a bit in how well they hold onto every piece of a complex instruction versus quietly dropping or blending details together.
If you regularly work with detailed, multi-part prompts, character sheets, specific scene compositions, layered instructions, model behavior under that kind of load is worth paying attention to directly, rather than assuming every anime-focused model handles complexity the same way.
Multi-character and Specialized Tasks
A model that’s excellent at rendering one character beautifully doesn’t automatically carry that strength into a scene with two or three characters interacting. Multi-character composition asks for something different, consistent proportions across multiple figures, coherent spatial relationships, clear visual separation between characters so the scene doesn’t collapse into a confusing tangle of limbs and clothing.
This is where a lot of disappointment happens with otherwise solid tools. A creator picks a model based on how gorgeous its single-character portraits look, then uses that same model for a two-character scene and can’t figure out why things suddenly feel off, merged silhouettes, inconsistent scale between the characters, a background that competes with both figures instead of supporting them. The model didn’t get worse. It’s just being asked to do a genuinely different job than the one it was chosen for. The practical takeaway is to treat this as its own category worth testing separately rather than assuming your favorite single-character model will just extend cleanly to group scenes. A model that’s your go-to for solo character portraits might not be your best choice the moment a second character enters the frame.
Where PixAI Fits

PixAI is a useful example of what task-based model selection actually looks like in practice, because it offers multiple anime-focused models rather than a single one-size-fits-all option, letting you match a model to what you’re actually trying to make instead of forcing every task through the same pipeline. Tsubaki.3 is one option worth knowing about among that lineup, useful for certain anime generation tasks, though it’s just one entry in a broader set rather than a single model meant to replace everything else.
If you want to go deeper on how these models differ in practice, or how model choice relates to LoRA use specifically, PixAI’s anime model guide and its breakdown of models versus LoRAs both cover that ground in more detail than a single article can.
How to Test a Model Yourself
The most reliable way to actually understand model behavior isn’t reading about it, it’s running a small, controlled comparison yourself. Pick one task you do often, a character portrait, a specific scene type, whatever’s actually relevant to your work. Use the same or a very similar prompt across two or three different models. Then judge the results against specific criteria, did it follow the specific details you asked for, did the character rendering match your intent, did the composition hold together, rather than just going with whichever result looks prettiest at a glance.
“Prettiest” is a trap here, honestly, because a gorgeous image that ignores half your prompt isn’t actually the better result for character or scene work, even if it’s the one that catches your eye first. Specific criteria tied to what you actually needed will tell you more than a gut reaction will.
This kind of test doesn’t need to be elaborate to be useful. Even a quick side-by-side, the same prompt run through two models, laid next to each other, is usually enough to reveal whether a model’s tendencies actually line up with what you’re trying to make. Do this a few times across the tasks you find yourself repeating most often, and you’ll start to build a mental map of which model fits which job, which is a far more useful thing to know than which model happened to launch most recently.
Conclusion
The prompt is only half the equation. The model interpreting it shapes style, character rendering, composition, and how well complex instructions actually survive into the final image, sometimes more than the wording of the prompt itself. Instead of defaulting to whatever model is newest or most talked about, it’s worth treating model choice as part of the creative decision for whatever you’re actually making. Next time a result doesn’t match what you pictured, try a different model with the same prompt before assuming the fix has to be in your wording, and pay attention to which models tend to fit which of your recurring tasks.


